Search This Blog

Tuesday, September 17, 2019

Wordpress - Starting a blog/website - Cheat Sheet


Monday, January 12, 2015

25 Math Concepts You Absolutely Need to Know


  •  The area of a circle is A = πr2, where r is the radius of the circle.
  •  The circumference of a circle is C = 2πr, where r is the radius of the circle. The circumference can
    also be expressed as πd, because the diameter is always twice the radius.
  •  The area of a rectangle is A = lw, where l is the length of the rectangle and w is the width of the
    rectangle.
  •  The area of a triangle is A = ½bh, where b is the base of the triangle and h is the height of the
    triangle.
  •  The volume of a rectangular prism is V = lwh, where l is the length of the rectangular prism, w is
    the width of the rectangular prism, and h is height of the rectangular prism.
  •  The volume of a cylinder is V = πr2h, where r is the radius of one of the bases of the cylinder and
    h is the height of the cylinder.
  •  The perimeter is the distance around any object.
  •  The Pythagorean Theorem only applies to right angles and states that c2 = a2 + b2, where c is the hypotenuse of the triangle and
    a and b are two sides of the triangle. 
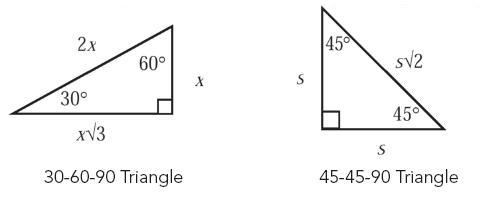
  •  The following are angle measures and side lengths for Special Right Triangles:
  •  In an equilateral triangle, all three sides have the same length, and each of the angles equals 60°.
  •  In an isosceles triangle, two sides have the same length, and the angles opposite those sides are
    congruent.
  •  The complete arc of a circle has 360°.
  •  A straight line has 180°.
  •  A prime number is any number that can only be divided by itself and 1.
  •  Squaring a negative number yields a positive result.
  •  To change any fraction to a decimal, divide the numerator by the denominator.
  •  If two numbers have one or more divisors in common, those are the common factors of the
    numbers.
  •  To calculate the mean, or average, of a list of values, divide the sum of the values by the number
    of values in the list.
  •  The median is the middle value of a list of numbers that is in either ascending or descending
    order.
  •  The mode is the value that appears the greatest number of times in a list.
  •  A ratio expresses a mathematical comparison between two quantities. (1/4 or 1:4)
  •  A proportion is an equation involving two ratios. (1/4 = x/8 or 1:4 = x:8)
  •  When multiplying exponential expressions with the same base, add the exponents.
  •  When dividing exponential expressions with the same base, subtract the exponents.
  •  When raising one power to another power, multiply the exponents.

Source: Benchprep.com

Please visit my other blogs too: http://edwardanil.blogspot.com for information and http://netsell.blogspot.com for internet marketing. Thanks !!

Tuesday, January 06, 2015

How to make your Wordpress site secure


HOSTING

•  Beware cheap ($5-$10/month) shared hosting accounts.
•  Look for hosts with experience hosting WordPress sites.
•  Look for hosts with solid support.
•  Look for hosts that are transparent: who communicate quickly and post issues online.
•  Make sure your host does regular backups that you can access.
•  Call your potential host to find out which versions of Apache web server, MySQL, and PHP they’re running. Check the version release dates with a Google search.
•  Ask your host for written documents containing their server data backup, failover, and update or maintenance policy. If they don’t have them, find another host.
•  Recommended hosts: WP Engine and ZippyKid


HARDENING AND PROTECTING WORDPRESS

•  To harden your WordPress install, follow these steps.
•  Keep WordPress, themes, and plugins up to date. Always. Period.
•  If you’re unsure about how to update WordPress, themes, and plugins, hire someone to do it for you.
•  Backup your site before you update WordPress, themes, and/or plugins.
•  Disable unused user accounts.
•  Never use “Admin” as your username. Ever.
•  Grant users the minimum privilege they need to do their jobs.
•  Require strong passwords.
•  Use 1Password or KeePass to create strong passwords.
•  Use a different, strong password for every site log in.
•  Lock down the WordPress admin dashboard (/wp-admin) using an .htaccess file.
•  Use SFTP to access your web host.
•  Enable SSL on your WP install.
•  Change your passwords once a month. Set a reminder in your calendar if you have to.
•  Do backups. Recommended: BackupBuddy, VaultPress
•  Set file permissions at 644 and 755 for folders.
•  Ensure that the permissions on wp-config.php are not world readable especially in a shared hosting environment.
•  Consider adding HTTP authentication to your /wp-admin/ area.
•  Read Sucuri.net’s blog.
•  Read Google’s security blog. 


CHOOSING THE RIGHT PLUGIN

•  Look for WordPress Plugin API hooks, actions, and filters.
•  Look for properly sanitized data and MySQL statements, unique namespace items, use of the Settings API for any plugin settings or options. 
•  Look for plugins that use nonces instead of browser cookies.
•  Check out how quickly the developer responds to support requests.
•  Check out forum threads to see how well the plugin is supported.
•  Is the developer a known and respected member of the community?
•  Look for a plugin that does one or two tasks really well.
•  If two plugins do similar things, choose the one with the higher download count.

YOU’VE BEEN HACKED. NOW WHAT?

•  Take the site offline. Now. That way you avoid getting a bad rap from search engines and antivirus programs.
•  Let your web host know what happened.
•  Make a full backup of the infected site. It’s helpful for reviewing what happened and in case you mess up something during the repair.
•  Change all of your passwords and the authentication keys in the wp-config.php.
•  Remove any old themes, plugins, and unused code from your server.
•  Update all code on your server. Re-install WordPress so all of the WordPress files are overwritten with fresh copies.
•  Reinstall themes or plugins with fresh copies to make sure no malicious code was inserted. 
•  Check that the file permissions on your files are correct, especially wp-config.php and uploads.
•  Remove the rogue code and make sure you check all sites on your hosting account. There are tools that can help scan and clean the infection such as VaultPress. Exploit  Scanner also scans for certain exploits.
•  If you don’t have the ability to fix the infected files the best thing to do is restore from a recent clean backup.
•  Check your server access logs. Search for any bad file names that you found on your server, patterns passed as query strings, or dates/times that may clue you in to when the attack happened. 

Source: CodePoet.com

Please visit my other blogs too: http://edwardanil.blogspot.com for information and http://netsell.blogspot.com for internet marketing. Thanks !!

Sunday, January 15, 2012

Tips on how to avoid or resolve deadlocking on your SQL Server

Deadlocking occurs when two user processes have locks on separate objects and each process is trying to acquire a lock on the object that the other process has. Usualy, they have different incompatible locks which are illegal or conflict (as per the compatible mode on locks).When this happens, SQL Server identifies the problem and ends the deadlock by automatically choosing one process and aborting the other process, allowing the other process to continue. The aborted transaction is rolled back and an error message is sent to the user of the aborted process. Generally, the transaction that requires the least amount of overhead to rollback is the transaction that is aborted.

Identify Deadlock:
  1. Using SQL Profiler
  2. Using System_health extended event(It highly depends on the ring buffer)
  3. Using Server side trace (DBCC TRACEON (1204) )
  4. Using SQL Error Log with a trace
  5. Predefined notification functionalities to log the deadlock info using service broker, extended events etc.
Here are some tips on how to avoid/resolve deadlocking on your SQL Server:
  1. Ensure the database design is properly normalized.
  2. Have the application access server objects in the same order each time.
  3. During transactions, don’t allow any user input. Collect it before the transaction begins.
  4. Avoid cursors.
  5. Keep transactions as short as possible. One way to help accomplish this is to reduce the number of round trips between your application and SQL Server by using stored procedures or keeping transactions with a single batch. Another way of reducing the time a transaction takes to complete is to make sure you are not performing the same reads over and over again. If your application does need to read the same data more than once, cache it by storing it in a variable or an array, and then re-reading it from there, not from SQL Server.
  6. Reduce lock time. Try to develop your application so that it grabs locks at the latest possible time, and then releases them at the very earliest time.
  7. If appropriate, reduce lock escalation by using the ROWLOCK or PAGLOCK.
  8. Consider using the NOLOCK hint to prevent locking if the data being locked is not modified often.
  9. If appropriate, use as low of an isolation level as possible for the user connection running the transaction.
  10. Consider using bound connections.
  11. Adding missing indexes to support faster queries
  12. Dropping unnecessary indexes which may slow down INSERTs for example
  13. Redesigning indexes to be "thinner", for example, removing columns from composite indexes or making table columns "thinner" (see below)
  14. Adding index hints to queries appropriately(I dont prefer this mostly, but it has got its own scope)
  15. Redesigning tables with "thinner" columns like smalldatetime vs. datetime or smallint vs. int
  16. Modifying the stored procedures to access tables in a similar pattern
  17. Keeping transactions as short and quick as possible: "mean & lean"
  18. Removing unnecessary extra activity from the transactions like triggers
  19. Removing JOINs to Linked Server (remote) tables if possible
  20. Implementing regular index maintenance; usually weekend schedule suffices; use FILLFACTOR = 80 for dynamic tables (Needs a good evaluation)
The list really goes on. The solution will vary from situation to situation.

Tuesday, April 26, 2011

Cloud development: 9 gotchas to know before you jump in

Whether developing, testing, or deploying your apps in the cloud, you have to unlearn some beliefs and learn new ones to make it work

Application development and testing in the cloud are gaining popularity, as more businesses launch public and private cloud computing initiatives. Cloud development typically includes integrated development environments, application lifecycle management components (such as test and quality management, source code and configuration management, continuous delivery tools), and application security testing components.

Although technology executives and developers with experience in cloud-based development say there are clear benefits to developing in these environments -- such as costs savings and increased speed to market -- they also caution that there are challenges and surprises to look out for.

[ Get the no-nonsense explanations and advice you need to take real advantage of cloud computing in InfoWorld editors' 21-page Cloud Computing Deep Dive PDF special report. | Stay up on the cloud with InfoWorld's Cloud Computing Report newsletter. ]


Gotcha 1: The cloud doesn't always work like the "real world"
Developers might find that the configuration they use in production is hard to replicate on cloud services. For example, with an application you develop in the cloud before bringing back to run locally, you might need to test against a legacy system that you can't simply copy onto a cloud service

Gotcha 2: Some apps aren't ideal for development in the cloud
The more hard-to-access or hard-to-replicate systems an application integrates with, the more difficult it is to develop and test it on cloud computing resources

Gotcha 3: Developers often dislike the unfamiliar cloud territory
Cloud computing is still relatively new to a lot of organizations, and it can be a disruptive technology, including in the development arena. 

Gotcha 4: Lack of documentation hinders cloud developers
There is a lack of documentation to help developers understand the cloud and the tools and resources that can be used to build applications in that environment.

Gotcha 5: Network issues can bedevil private cloud environments 
Developing in the cloud sometimes means developing in your own private cloud, which may not have the multitenancy and load-movement capabilities that keep your applications available 24/7. Other issues that can affect development and testing involve network delays and latency and the size of network pipes, especially in certain parts of the world. 

Gotcha 6: It's easy to let the meter run unnecessarily on the cloud
Another potential problem is wasting money on cloud fees. Developers can easily forget or neglect to turn off virtual machines they aren't using. When it was on an in-house, capitalized server, this was no big deal. But when it is on usage-metered, leased resources as with public cloud computing, this is a waste of money

Gotcha 7: Cloud licenses can contain surprising deployment restrictions 
Among the nontechnical issues with the cloud that can have an impact on development are licensing restrictions.

Gotcha 8: Integration can be harder to troubleshoot
Integrating new applications with existing ones can be a key part of the development process, and the cloud brings even more challenges from an integration perspective.

Gotcha 9: The cloud's fast pace of change can be hard to keep up with 
Being on a quickly evolving cloud development platform, like Azure, means it's necessary to update best practices frequently

Despite the learning curve, cloud development is appealing
Despite the potential challenges, for many organizations application development in the cloud rather than sticking with traditional methods makes sense, for the same reasons that cloud computing in general makes sense: elasticity of resources and cost, and reduced operational complexity, both of which lead to shorter completion time.

This article, "Cloud development: 9 gotchas to know before you jump in," was originally published at InfoWorld.com. 


Follow edwardanil on Twitter

Wednesday, January 06, 2010

Data access optimization steps in SQL Server


Use Indexing
  • Apply proper indexing in the table columns in the database
    • Make sure that every table in your database has a primary key.
    • Create non-clustered indexes on columns which are, frequently used in the search criteria, Used to join other tables, Used as foreign key fields , Of having high selectivity (Column which returns a low percentage (0-5%) of rows from a total number of rows on a particular value) or Used in the ORDER BY clause
  • Create appropriate covering indexes
    • Use Database Tuning Advisor’s help while creating covered index
  • Defragment indexes if fragmentation occurs
It's really tempting to create index on all eligible columns in your database tables. But, if you are working with a transactional database (An OLTP system where update operations take place most of the times), creating indexes on all eligible columns might not be desirable every time. In fact, creating heavy indexing on OLTP systems might reduce overall database performance (As most operations are update operations, updating data means updating indexes as well).

A rule of thumb can be suggested as follows: If you work on a transactional database, you should not create more than 5 indexes on the tables on an average. On the other hand, if you work on a Data warehouse application, you should be able to create up to 10 indexes on the tables on an average.


Re-factor TSQLs and apply best practices
  • Move TSQL codes from application into the database server
  • Identify inefficient TSQLs, re-factor and apply best practices
    • Don’t use “SELECT*" in SQL Query
    • Avoid unnecessary columns in SELECT list and unnecessary tables in join conditions
    • Do not use the COUNT() aggregate in a subquery to do an existence check
    • Try to avoid joining between two types of columns
    • Try to avoid deadlocks 
    • Write TSQLs using “Set based approach” rather than using “Procedural approach” 
    • Try not to use COUNT(*) to obtain the record count in the table 
    • Try to avoid dynamic SQLs
    • Try to avoid the use of Temporary Tables, try to use Table variables.
    • Instead of LIKE search, Use Full Text Search for searching textual data 
    • Try to use UNION to implement “OR” operation 
    • Use VARCHAR(MAX), VARBINARY(MAX) and NVARCHAR(MAX) 
    • Do not call functions repeatedly within your stored procedures, triggers, functions and batches.
    • Try to avoid the use of triggers.
    • Try to avoid nested transaction.
    • Understanding the query execution plan
    • Getting rid of the unnecessary Text column in the SELECT list
Apply advanced indexing and denormalization
  • Apply some advanced indexing techniques
    • Implement computed columns and create index on these
    • Create "Indexed Views"
    • Create indexes on User Defined Functions (UDF), using computed columns
    • Create indexes on XML columns
  • Apply de-normalizations, use history tables and pre-calculated columns
Diagnose database performance problems
  • Diagnose performance problem, use SQL Profiler and Performance Monitoring tool effectively.
Optimize database files and apply partitioning
  • Organize the file groups and files in the database
  • Apply partitioning in the big fat tables


Original Source: M.M.Al-Farooque Shubho

Thursday, December 18, 2008

Importance of CSS in web development

CSS style sheets have made it easier to handle web pages during web development. CSS or Cascading Style Sheets as the name suggests is a style sheet that allows you to easily link to other documents in your website. It allows you to retain control over the various elements in different web pages of your website.

CSS only defines the structure and content presentation of a website it has nothing to do with the design of a website. A single CSS sheet can control the font, positioning, colour and style information of an entire website.

9 advantages of using CSS
* Web pages are easier to load and uses less bandwidth
CSS style sheets are preferred by web developers for website development because they are lighter than table layouts, which consumes lots of bandwidth. The style sheet is downloaded only once and stored in the cache memory, so subsequent pages load faster.

* A CSS style sheet compliments well with HTML
HTML is insufficient when used independently in website development, but when combined with CSS they can result in technically stronger web pages.

* CSS allows you to position your element anywhere in the webpage
Web developers love to use CSS because it allows them to position their element where ever they want in the web page. If during any phase of web development the developer feels that particular links or columns are not going well with the situation then it becomes easier for them to position them easily using CSS. CSS reduces the risks associated with maintenance of the website.

* CSS is compatible with all web browsers
CSS is combined with HTML or XHTML by web developers for web application development because it is compatible with all web browsers. The sites that use CSS appear similar in all the web browsers.

* CSS can be used to create print friendly web pages
Most of the web developers love to use CSS for building their HTML based web applications because they allow them to create print friendly web pages. These web pages can be easily printed. The colours, images and other things which are difficult to be printed can be eliminated and printed easily.

* CSS style sheets allows the user to customize the webpage
Now days many websites allow the user to change the layout of the website without affecting the content. The CSS style sheets which are stored externally allow the user to make requisite changes by themselves. Most of the modern browsers give user the liberty to define their own style sheets like changing some font properties etc.

* CSS style sheets makes it easier for your website to feature in search engines
The CSS style sheets are favoured by web developers because they allow them to position their elements as per their wish anywhere in web application. Positioning helps to project the main contents first, so that it is easily captured by web spiders. CSS also gives cleaner HTML codes thus cutting down the job of web spider to search the real content from junk code.

* CSS allows the web pages to have absolute consistency
One of the reasons for using CSS during web development is that they allow consistency to all web pages. All the expressions and texts will get their characteristics from external style sheet. Web developers need not to worry about the change in characteristics of the elements because they can be easily altered at any stage of web development by using CSS.

* CSS lends portability to content
By using CSS you can make separate style sheets for different media. This provides you the great flexibility in presenting your content. CSS allows you to redefine the characteristics of elements in a website to suit the need of the situation. For e.g.: A separate style sheet will allow you to redefine the characteristics of certain elements so that they are easier to be printed. Also the user will never come to know that you had restructured the characteristics for their benefit.

CSS is created to make the things easier for your website and also to give you control over different elements in your website. Utilizing benefits of CSS will give you popular user friendly web pages.

To appreciate the beauty and flexibility of CSS, check out the site, CSSZenGarden.com
The Zen Garden aims to excite, inspire, and encourage participation. To begin, view some of the existing designs in the list. Clicking on any one will load the style sheet into this very page. The code remains the same, the only thing that has changed is the external .css file.

CSS allows complete and total control over the style of a hypertext document. The only way this can be illustrated in a way that gets people excited is by demonstrating what it can truly be, once the reins are placed in the hands of those able to create beauty from structure. To date, most examples of neat tricks and hacks have been demonstrated by structurists and coders. Designers have yet to make their mark. This needs to change.

Original Source:
http://support.fuchsiasoft.org/importance-of-css-in-web-development-t67.html

Saturday, February 09, 2008

SQL Injection

SQL injection is a technique that exploits a security vulnerability occurring in the database layer of an application. The vulnerability is present when user input is either incorrectly filtered for string literal escape characters embedded in SQL statements or user input is not strongly typed and thereby unexpectedly executed. It is in fact an instance of a more general class of vulnerabilities that can occur whenever one programming or scripting language is embedded inside another.

SQL Injection: A Simple Example
Take a simple login page where a legitimate user would enter his username and password combination to enter a secure area to view his personal details or upload his comments in a forum.

When the legitimate user submits his details, an SQL query is generated from these details and submitted to the database for verification. If valid, the user is allowed access. In other words, the web application that controls the login page will communicate with the database through a series of planned commands so as to verify the username and password combination. On verification, the legitimate user is granted appropriate access.

Through SQL Injection, the hacker may input specifically crafted SQL commands with the intent of bypassing the login form barrier and seeing what lies behind it. This is only possible if the inputs are not properly sanitized (i.e., made invulnerable) and sent directly with the SQL query to the database. SQL Injection vulnerabilities provide the means for a hacker to communicate directly to the database.

The technologies vulnerable to this attack are dynamic script languages including ASP, ASP.NET, PHP, JSP, and CGI. All an attacker needs to perform an SQL Injection hacking attack is a web browser, knowledge of SQL queries and creative guess work to important table and field names. The sheer simplicity of SQL Injection has fueled its popularity.

Forms of SQL injection vulnerabilities
Incorrectly filtered escape characters
This form of SQL injection occurs when user input is not filtered for escape characters and is then passed into a SQL statement. This results in the potential manipulation of the statements performed on the database by the end user of the application.

Incorrect type handling
This form of SQL injection occurs when a user supplied field is not strongly typed or is not checked for type constraints. This could take place when a numeric field is to be used in a SQL statement, but the programmer makes no checks to validate that the user supplied input is numeric.

Blind SQL Injection
Blind SQL Injection is used when a web application is vulnerable to SQL injection but the results of the injection are not visible to the attacker. The page with the vulnerability may not be one that displays data but will display differently depending on the results of a logical statement injected into the legitimate SQL statement called for that page. This type of attack can become time-intensive because a new statement must be crafted for each byte recovered. A tool called Absinthe can automate these attacks once the location of the vulnerability and the target information has been established.

Preventing SQL Injection
To protect against SQL injection, user input must not directly be embedded in SQL statements. Instead, user input must be escaped, or parameterized statements must be used.

Using Parameterized Statements
Parameterized statements use parameters (sometimes called placeholders or bind variables) instead of embedding user input in the statement. In many cases, the SQL statement is fixed. The user input is then assigned (bound) to a parameter.

Enforcing the Use of Parameterized Statements
There are two ways to ensure an application is not vulnerable to SQL injection: using code reviews (which is a manual process), and enforcing the use of parameterized statements. Enforcing the use of parameterized statements means that SQL statements with embedded user input is rejected at runtime.

How to check for SQL injection vulnerabilities
Securing your website and web applications from SQL Injection involves a three-part process:

   1. Analysing the present state of security present by performing a thorough audit of your website and web applications for SQL Injection and other hacking vulnerabilities.
   2. Making sure that you use coding best practice sanitizing your web applications and all other components of your IT infrastructure.
   3. Regularly performing a web security audit after each change and addition to your web components.

Furthermore, the principles you need to keep in mind when checking for SQL Injection and all other hacking techniques are the following: “Which parts of a website we thought are secure are open to hack attacks?” and “what data can we throw at an application to cause it to perform something it shouldn’t do?”.

Checking for SQL Injection vulnerabilities involves auditing your website and web applications. Manual vulnerability auditing is complex and very time-consuming. It also demands a high-level of expertise and the ability to keep track of considerable volumes of code and of all the latest tricks of the hacker’s ‘trade’.

The best way to check whether your web site and applications are vulnerable to SQL injection attacks is by using an automated and heuristic web vulnerability scanner.

An automated web vulnerability scanner crawls your entire website and should automatically check for vulnerabilities to SQL Injection attacks. It will indicate which URLs/scripts are vulnerable to SQL injection so that you can immediately fix the code. Besides SQL injection vulnerabilities a web application scanner will also check for Cross site scripting and other web vulnerabilities.

Resources:
  • http://en.wikipedia.org/wiki/SQL_injection
  • http://www.unixwiz.net/techtips/sql-injection.html
  • http://www.acunetix.com/websitesecurity/sql-injection.htm
  • http://ferruh.mavituna.com/sql-injection-cheatsheet-oku/
  • http://www.acunetix.com/websitesecurity/sql-injection2.htm

Wednesday, January 30, 2008

Tips for Writing High-performance SQL

Tips for Writing High-performance SQL
These tips apply broadly when writing high-performance stored procedures. Unfortunately, unlike some tips, you can't simply apply most of them without first considering the nature and schema of the data you're querying.

  1. Avoid using cursors (as well as other looping structures) as much as possible. Cursors are inefficient, and database engines usually don't have the best loop implementations in terms of performance.

    On the database side, you can usually replace code involving cursors with aggregate SQL statements (SELECT, INSERT, and UPDATE) that use vector tables. All database engines are heavily optimized for aggregate statements, so even if a loop is unavoidable, it is always better to execute a few aggregate statements in a loop with a small number of iterations, than to create a cursor and execute simple statements over a large number of iterations.

    Even if initial performance tests, especially with a small amount of data, show cursors to be more efficient than a complex aggregate statement, it is worthwhile to try to optimize the operation by breaking it into smaller portions or using other approaches—unless you can guarantee that the data value will stay small. Cursor approaches will not scale.

  2. Filter data wisely. One alternative to using cursors uses a fall-through approach, filtering and aggregating data in multiple steps via a set of data storages, which could be physical tables, temporary tables, or table variables. It is usually best to include some aggregate filters into aggregate statements to filter out the majority of data in one simple shot whenever necessary, working on smaller amounts of data. Then you can proceed with joining and filtering, making sure to keep the number of join permutations under control at all times.

  3. It is usually more efficient to execute multiple statements with one condition than a single statement with multiple OR conditions when executing UPDATE and DELETE statements against permanent database tables that can be accessed by multiple users simultaneously. This tip is especially important from the scalability point of view; from the performance point of view the difference is usually marginal. The major reason for the tip is the locking of the database records and the lock escalations that occur behind the scenes.

  4. Make wise distinctions between temp tables and table variables. Table variables are in-memory structures that may work from 2-100 times faster than temp tables. But keep in mind that access to table variables gets slower as the volume of data they contain grows. At some point, table variables will overflow the available memory and that kills the performance. Therefore, use table variables only when their data content is guaranteed not to grow unpredictably; the breaking size is around several thousand records. For larger data volumes, I recommend temp tables with clustered indexes. Interestingly, I've found that a temp table with one clustered index is often faster than having multiple simple indexes. In contrast, multiple simple indexes with physical tables are often faster than one clustered index.

  5. Make careful distinctions between hard rules and assumptions. This is more of a business design tip, which applies more to code design than to performance and scalability design in general. In real life however, performance and scalability are generally the first things to suffer from improper design. When rules are implemented as assumptions, they usually cause unnecessary calculations to be performed, affecting performance. However, when assumptions are implemented as rules they tend to cause errors and algorithm failures, which usually requires an urgent redesign. That, in turn, is usually performed with business constraints and results in inefficient final algorithms. That's because bad design decisions are often corrected in a rush and without sufficient resources—sometimes under pressure from customers whose businesses are usually in a critical stage when problems are uncovered, but must continue operating during the process.

  6. Pay attention to join order. Using proper join order sometimes lets the database engine generate hints that execute joins with an optimal amount of records. Most database engines also support hard hints, but in most cases you should avoid using hard hints and let the database engine figure out the best way to do its job on its own.

  7. Be careful when joining complex views to other views and database tables in complex SELECT statements. When the database contains a significant amount of data, SQL Server engine tends to recalculate the execution plan of the resulting statement, which often results in an inefficient execution plan and may kill the performance. The most difficult part is that the behavior of SQL Server engine is inconsistent in that respect, and heavily depends on the database size, indexes, foreign keys, and other database structures and constraints. The consistent work-around is to pre-select data from the view into a temp table with the reasonable pre-filters, and then use that temp table in place of the underlying view.

  8. Create indexes on temp tables wisely. As mentioned in Tip 4, clustered indexes are usually the best in terms of performance for temp tables; however, there is a difference between creating the index before or after inserting data into the temp table. Creating the index before the insert complicates the insert, because the database engine must order the selection. For complex selections such as those mentioned in Tip 7, the extra ordering may overcomplicate the overall statement and drastically degrade the performance. On the other hand, creating the index after the insert forces the database engine to recalculate the execution plan of the stored procedure every time it is called. Therefore, the decision is always a trade-off and you should make it based on the relative costs of the two possibilities.

  9. In general, try to avoid execution plan recalculation. One common cause of recalculation occurs when the stored procedure contains several paths that depend on values passed in parameters. However, whether avoiding recalculation is possible depends on the complexity of the stored procedure and on other circumstances, such as those described in tip 8. When the engine does recalculate execution, performance always suffers; however, recalculating the execution plan of the caller does not force the execution plan recalculation of the called procedure (or view or function). Therefore, the workaround is to divide one stored procedure into multiple procedures (depending on the passed-in parameters), and then call the children from the parent conditionally. You should perform this subdivision very carefully though, because it can be a maintenance nightmare—but sometimes it seems to be the only way to achieve acceptable database performance and scalability.
Finally, although this isn't either a performance or a scalability tip, I urge you to format your stored procedure scripts legibly. It's best to agree on common practices such as clause order and formatting rules with your coworkers in advance. Not only does that help avoid errors, it also clearly shows the logical structure of the statements and often aids in figuring out faulty filters and joins.

This list of tips is certainly not exhaustive, but they probably cover the most important performance and scalability factors.

The original article could be read from the following link:
http://www.devx.com/dbzone/Article/33551/0/page/2

For an example solution (Sudoku Stored Procedure Script),  read from the following link:
http://www.devx.com/dbzone/Article/33551/0/page/3

Gene Pinski currently works as a Dev Lead at Pearson School Systems where he's responsible for several development areas of Chancery SMS in Burnaby, BC, Canada. His professional interests include developing business and web applications, and developing games. Find more about Gene from his web site.

Sunday, January 13, 2008

JavaScript Best Practices

Use Object Oriented JavaScript
• Provides better reusability of the code
• Enables your objects to be better organized
• Allow for dynamic loading of objects

Use Object Hierarchies to Organize JavaScript Objects to Avoid Name Collision
• In JavaScript there is the potential for object names to collide. In Java language, package names are used to prevent naming collisions
• JavaScript does not provide package names like Java however you can when writing components use objects and object hierarchies to organize related objects and prevent naming collision

Use the prototype property
• Use it to define shared behavior and to extend objects
• The prototype property is a language feature of JavaScript. The property is available on all objects

Write reusable JavaScript
• JavaScript should not be tied to a specific component unless absolutely necessary
• Consider not hard coding data in your functions that can be parameterized

Object Literals
• Object literals are objects defined using braces ({}) that contain a set of comma separated key value pairs much like a map in Java
• Example
{key1: "stringValue", key2: 2, key3: ['blue','green','yellow']}
• Object literals are very handy in that they can be used as arguments to a function
• Object literals should not be confused with JSON which has similar syntax

Load JavaScript On Demand
• If you have a large library or set of libraries you don't need to load everything when a page is loaded
• JavaScript may be loaded dynamically at runtime using a library such as JSAN or done manually by using AJAX to load JavaScript code and calling eval() on the JavaScript

Separation of content, CSS, and JavaScript
• A rich web application user interface is made up of
content (HTML/XHTML), styles (CSS), JavaScript
• Separating the CSS styles from the JavaScript is a practice which will make your code more manageable, easier to read, and easier to customize
• Place CSS and JavaScript code in separate files
• Optimize the bandwidth usage by having CSS and JavaScript file loaded only once

Reduce the size of JavaScript file
• Remove the white spaces and shortening the names of variables and functions in a file
• While in development mode keep your scripts readable so that they may be debugged easier
• Consider compressing your JavaScript resources when you deploy your application
• If you use a 3rd party JavaScript library use the compressed version if one is provided.
Example compression tool: ShrinkSafe

To read the actual article, you could download the pdf file from the following link.
http://www.javapassion.com/ajax/JavaScriptBestPractices.pdf

Tuesday, October 09, 2007

Cluster Computing and MapReduce

Lecture 1: Introducing Mapreduce and Cluster Computing
Distributed systems overview, review of synchronization and networking.


Lecture 2: The MapReduce programming model.
Overview of the MapReduce programming model.


Lecture 3: Distributed File Systems
Overview of distributed file systems with attention to the Google File System.


Lecture 4: Clustering Algorithms
Types of clustering algorithms, MapReduce implementations of K-Means and Canopy Clustering


Lecture 5: Graph Algorithms
Graph representations, distributed Pagerank, distributed Dijkstra.


Just as people are social animals, computers are social machines—the more, the merrier. Twenty or thirty years ago, large, centralized mainframes sat alone in sheltered bunkers in computer science departments and government offices alike, choking for hours on mere megabytes of data. Even with recent advances in server technology, large, centralized machines are still struggling to cope with today’s modern computational challenges, which now involve terabytes of data and processing requirements well beyond a single CPU (or two, or four, or eight). One computer just won’t hack it; these days, to support a new paradigm of massively parallel systems architecture, we need to break the machine out of its bunker and give it some friends.

In this age of “Internet-scale” computing, the new, evolving problems faced by computer science students and researchers require a new, evolving set of skills. It’s no longer enough to program one machine well; to tackle tomorrow’s challenges, students need to be able to program thousands of machines to manage massive amounts of data in the blink of an eye. This is how I, along with my good friend and mentor Ed Lazowska of the University of Washington’s CSE department, started to think about CS curricula and the obstacles to teaching a practical and authentic approach to massively parallel computing.

It's no easy feat. Teaching these methods effectively requires access to huge clusters and innovative new approaches to curricula. That's why we are pleased to announce the successful implementation of our Academic Cluster Computing Initiative pilot program at a handful of schools, including the University of Washington, Carnegie-Mellon University, Massachusetts Institute of Technology, Stanford University, the University of California at Berkeley and the University of Maryland. This pilot extends our expertise in large scale systems to strong undergraduate programs at the pilot schools, allowing individual students to take advantage of the hundreds of processors being made available. As the pilot progresses, we'll work with our technology partner IBM to shake the bugs out of the system so that we can expand the program to include more educators and academic researchers.

The future of computing is already taking shape on campuses today, and Google and IBM are thrilled to help inspire a new generation of computer scientists to think big. All of the course material developed by UW as well as other tools and resources to facilitate teaching this cutting- edge technology is available at http://code.google.com/edu. If you're a student wondering just what this sort of thing means for you, check out the five-part video lecture series (originally offered to Google Engineering interns) that introduces some of the fundamental concepts of large-scale cluster computing.

Earlier this year, the University of Washington partnered with Google to develop and implement a course to teach large-scale distributed computing based on MapReduce and the Google File System (GFS). The goal of developing the course was to expose students to the methods needed to address the problems associated with hundreds (or thousands) of computers processing huge datasets ranging into terabytes. I was excited to take the first version of the class, and stoked to serve as a TA in the second round.

But you can't program air, so Google provided a cluster computing environment to get us started. And since computers can't program themselves (yet?), UW provided the most essential component: students with sweet ideas for a huge cluster. After learning the ropes with these new tools, students finished the course by producing an impressive array of final projects, including an n-body simulator, a bot to perform Bayesian analysis on Wikipedia edits to search for spam, and an RSS aggregator that clustered news articles by geographic location and displayed them using the Google Maps API. Check out Geozette.

We are looking at ways to encourage other universities to get similar classes going, so we've also published the course material that was used at the University of Washington on Google Code for Educators. You're more than welcome to check out the Google Summer Intern video lectures on MapReduce, GFS, and parallelizing algorithms for large scale data processing. This summer I've been working on exposing these educational resources and other tools so that anyone can work on and think about cool distributed computing problems without the overhead of installing his or her own cluster. In that vein, we've released a virtual machine containing a pre-configured single node instance of Hadoop that has the same interface as a full cluster without any of the overhead. Feel free to give it a whirl.

We're happy to be able to expose students and researchers to the tools Googlers use everyday to tackle enormous computing challenges, and we hope that this work will encourage others to take advantage of the incredible potential of modern, highly parallel computing. Virtually all of this material is Creative Commons licensed, and we encourage educators to remix it, build upon it, and discuss it in the Google Code for Educators Forum.

Lastly, a quick shout out to the other interns who helped out on our team this summer: Aaron Kimball, Christophe Taton, Kuang Chen, and Kat Townsend. I'll miss you guys!

Resources:
http://google-code-updates.blogspot.com/2007/09/uw-and-google-teaching-in-parallel.html
http://code.google.com/edu/
http://code.google.com/edu/content/submissions/mapreduce-minilecture/listing.html
http://googleblog.blogspot.com/2007/10/let-thousand-servers-bloom.html